GenAI / RAG
Kubernetes Gated RAG
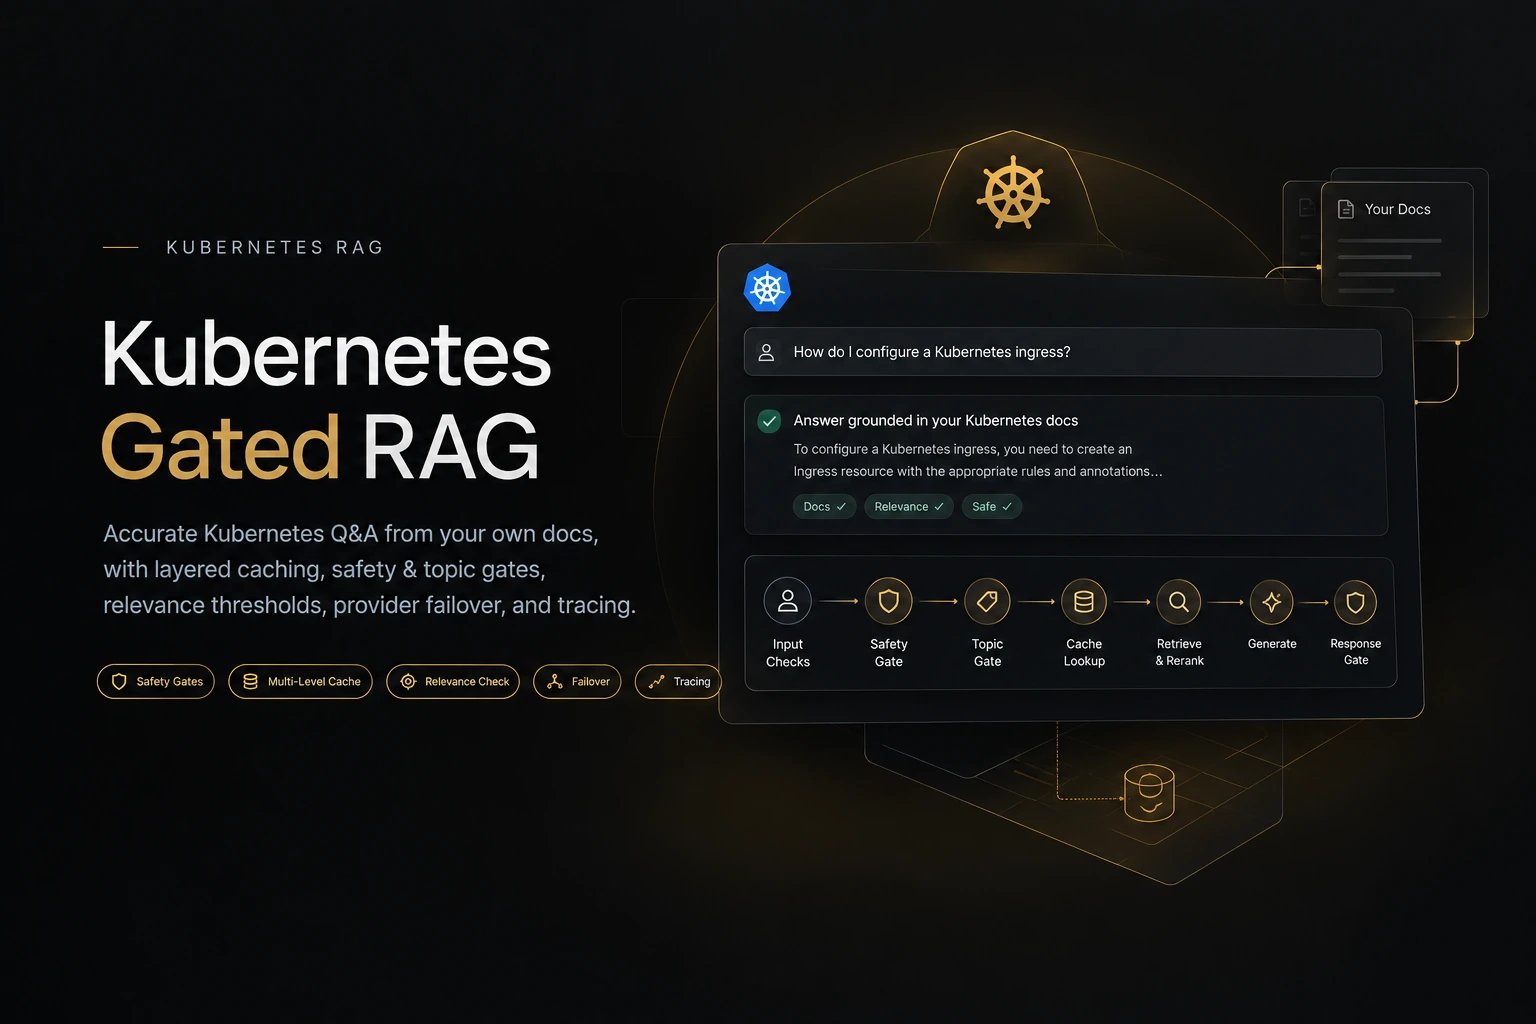
Kubernetes Q&A that answers only from the docs you ingest. A gate guards every stage, and infrastructure failures return an uncached outage message, not a guess.
AI/ML engineer building recommenders, RAG, agents, MLOps, and causal inference systems. Each project ships with tests, benchmarks, and documented limits.
I build ML and LLM systems end to end: retrieval, agents, recommenders, causal inference, and the MLOps around them. I report what the measurements show, including where the system falls short. Everything here runs on free-tier infrastructure.
Three of nine case studies. Each one lists what its evidence does not show.
GenAI / RAG
Kubernetes Q&A that answers only from the docs you ingest. A gate guards every stage, and infrastructure failures return an uncached outage message, not a guess.
AI Agents / MCP
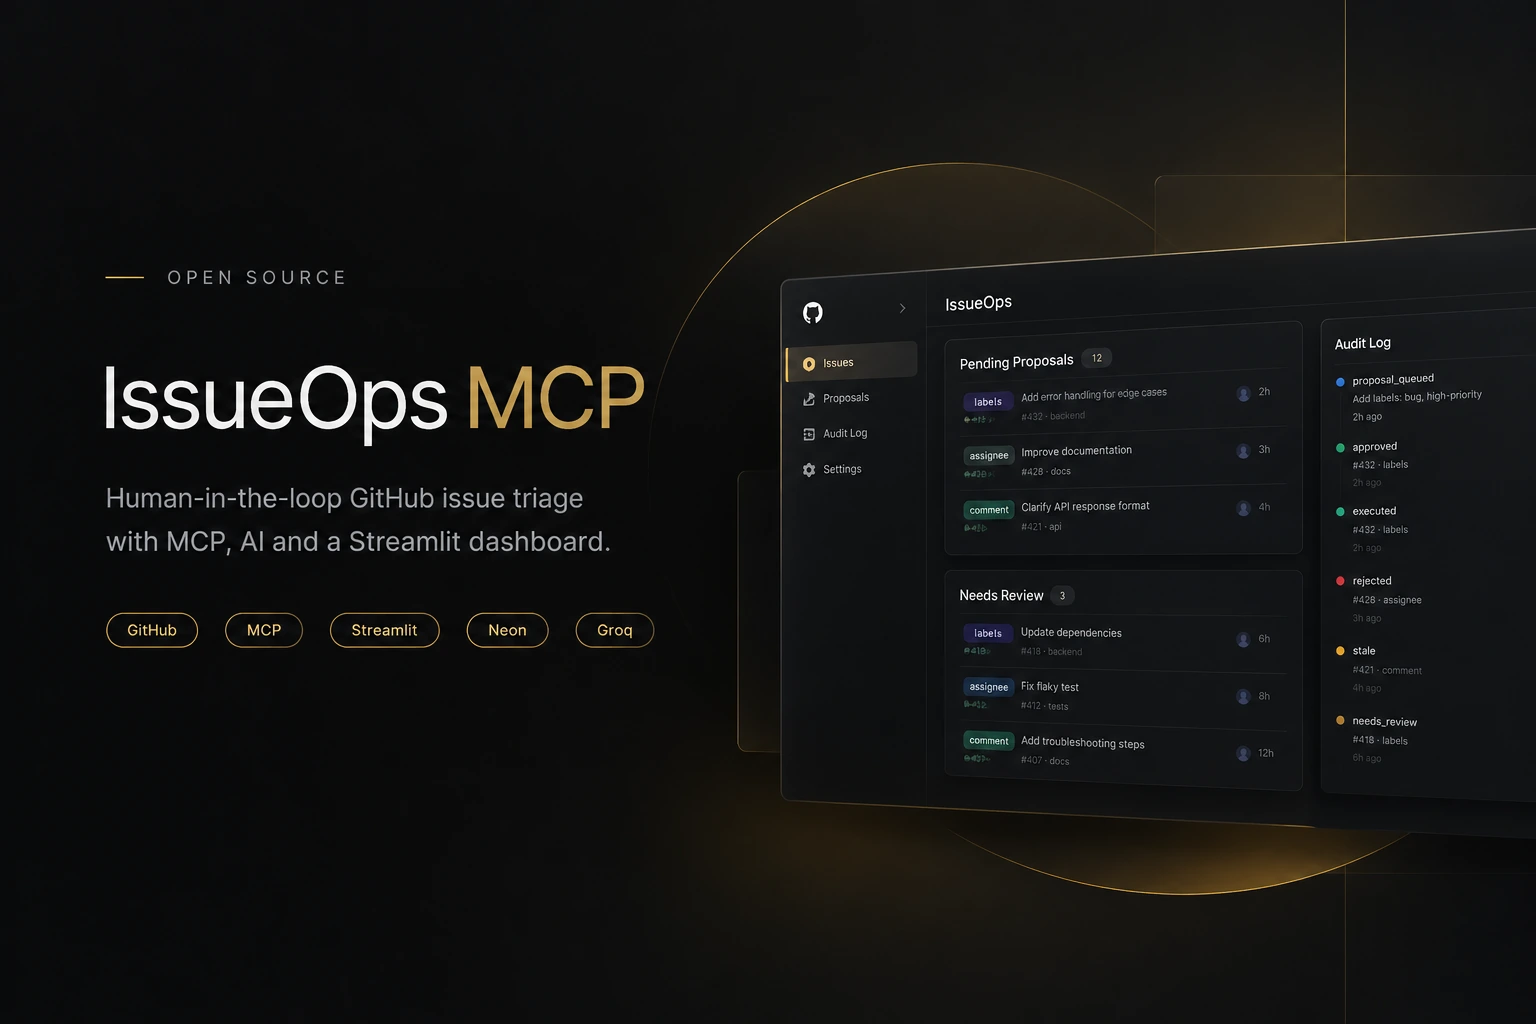
A GitHub issue triage system where the model can only propose. Nothing reaches GitHub until a person approves it, and every step is audit-logged.
MLOps
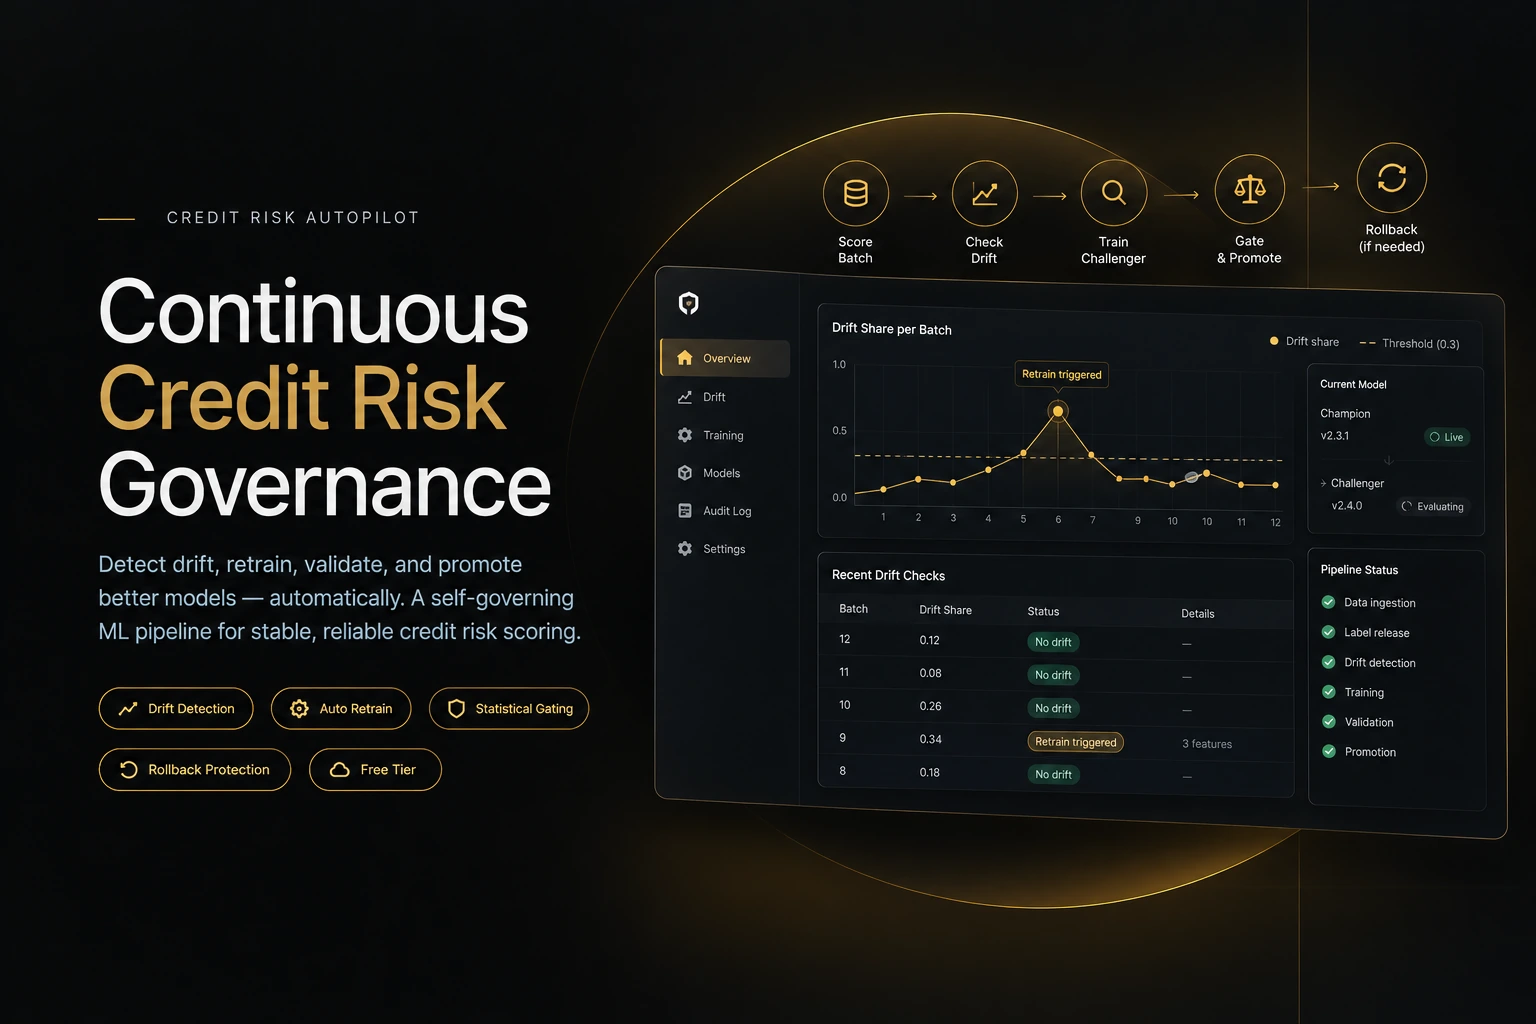
A credit-risk model that runs its own lifecycle: it detects drift, retrains a challenger, gates promotion with a bootstrap test, and rolls back if the old model wins.
Modeling, LLM systems, and the production tooling around them.
PythonSQLBashC++
FastAPIStreamlitPostgres (Neon)SupabaseSQLitepandasNumPyTableauPlotly
Power AnalysisWelch's t-testBenjamini-HochbergRosenbaum BoundsIPW / AIPWCATE (T-learner)QiniMcNemar / Bootstrap CIstatsmodelsscikit-uplift
RAGLangGraphMulti-Agent OrchestrationMCP (stdio server)QdrantFAISSFlashRankRagasNeMoGuardGroqNVIDIA NIMGemini API
MLflowDVCEvidentlyDrift Detection (K-S)Model Governance & RollbackGitHub ActionsCI/CDLogfireDockerAWS
XGBoostLightGBMscikit-learnPyTorchProphetSARIMAIsolation ForestALS / BPRTwo-Tower & SASRecSHAPOptuna
Bold marks the tools used most across the projects.
Where the work happened, and the record behind it.
Coding Blocks
Lovely Professional University, Punjab, India
If you are building something that needs a system tested as hard as it is trained, I would like to hear about it.
Nine end-to-end projects across LLM systems, MLOps, and applied statistics. Each ships with tests, an evaluation approach, and a written list of what it does not prove.
Showing 9 of 9 projects
GenAI / RAG
Kubernetes Q&A that answers only from the docs you ingest. A gate guards every stage, and infrastructure failures return an uncached outage message, not a guess.
AI Agents
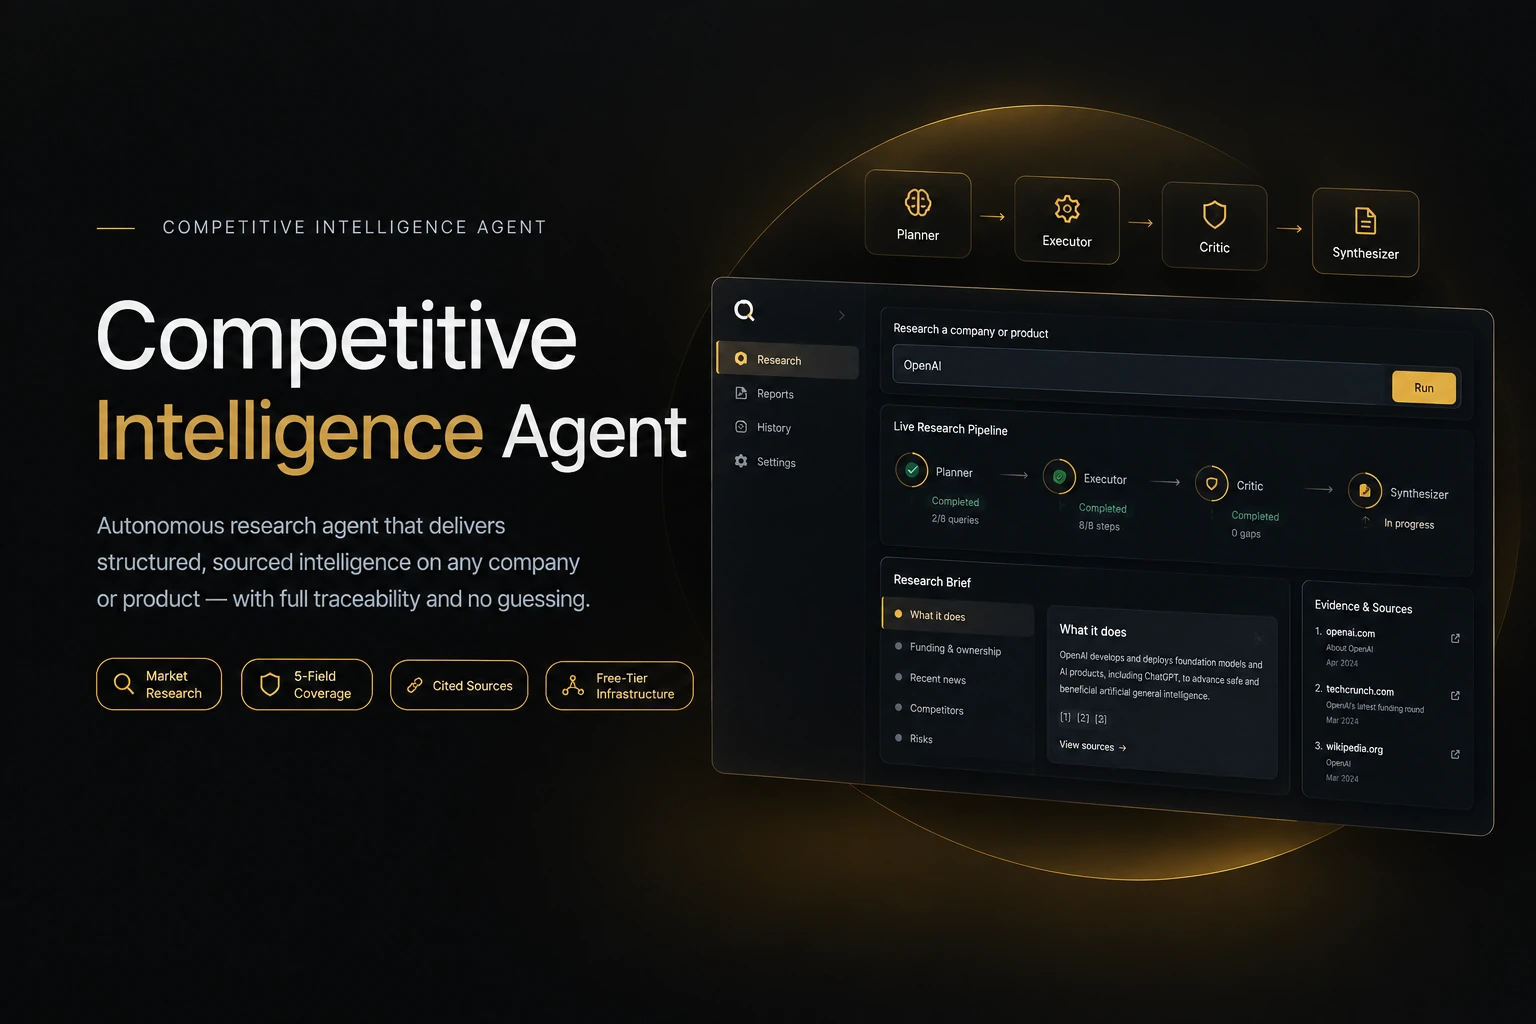
A research agent that turns a company name into a sourced brief. A Critic loop fills gaps, and anything unsourced is marked insufficient information.
AI Agents / MCP
A GitHub issue triage system where the model can only propose. Nothing reaches GitHub until a person approves it, and every step is audit-logged.
MLOps
A credit-risk model that runs its own lifecycle: it detects drift, retrains a challenger, gates promotion with a bootstrap test, and rolls back if the old model wins.
Predictive Modeling
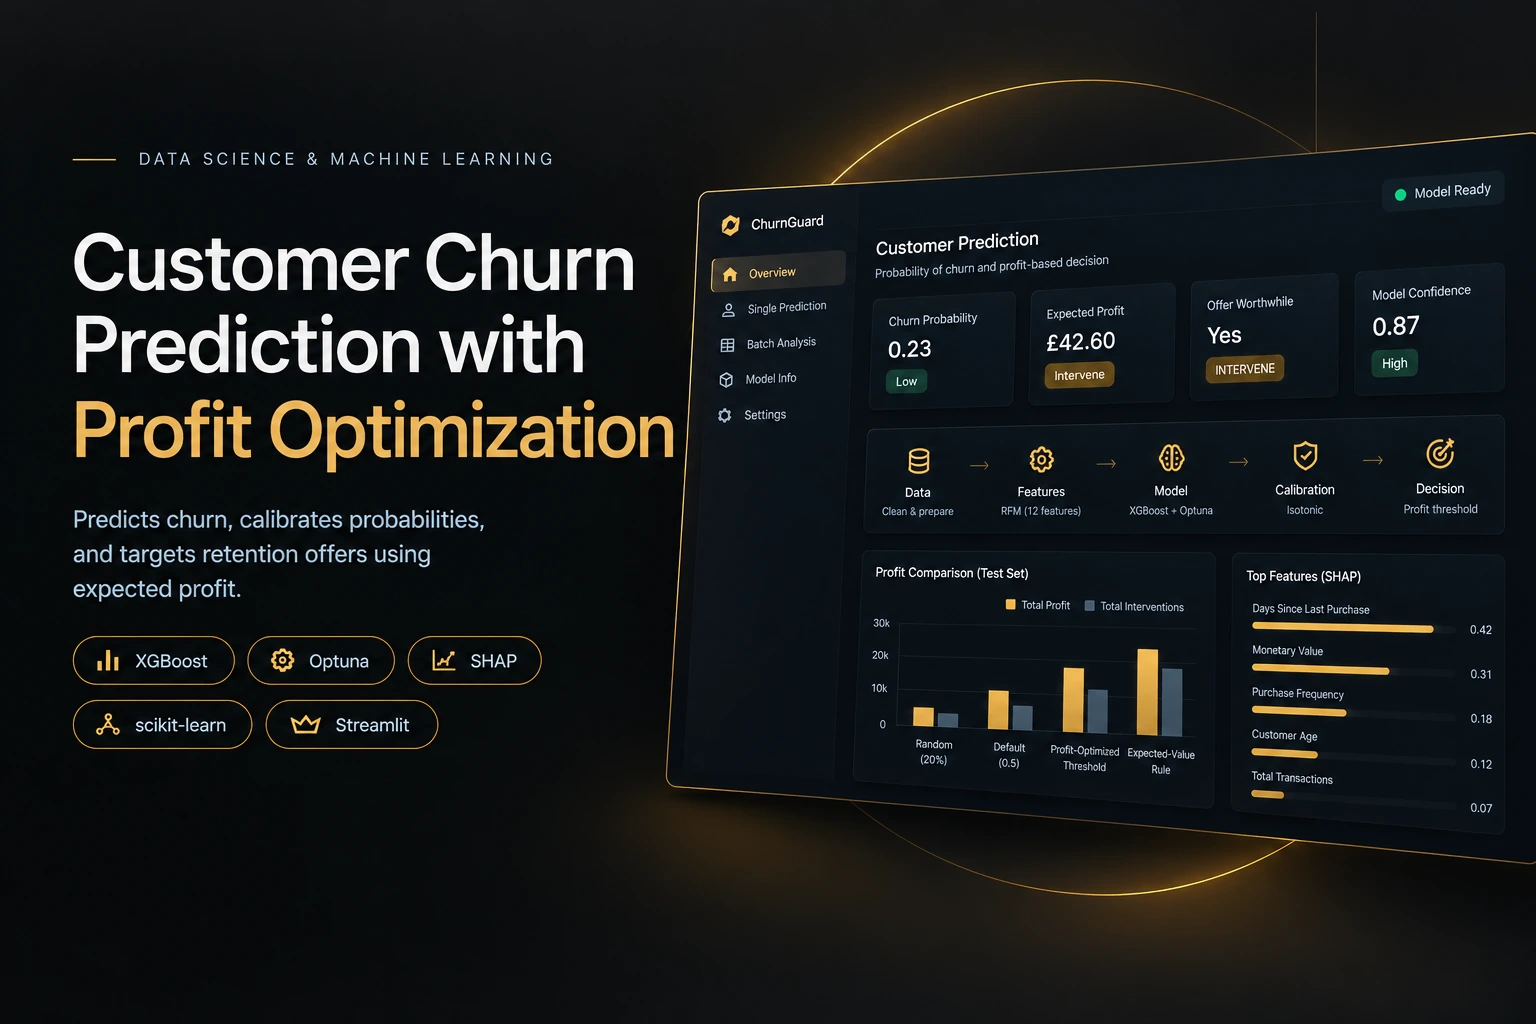
Predicts 90-day churn and targets a customer only when a retention offer's expected profit exceeds its cost, not by a raw probability cutoff.
Forecasting
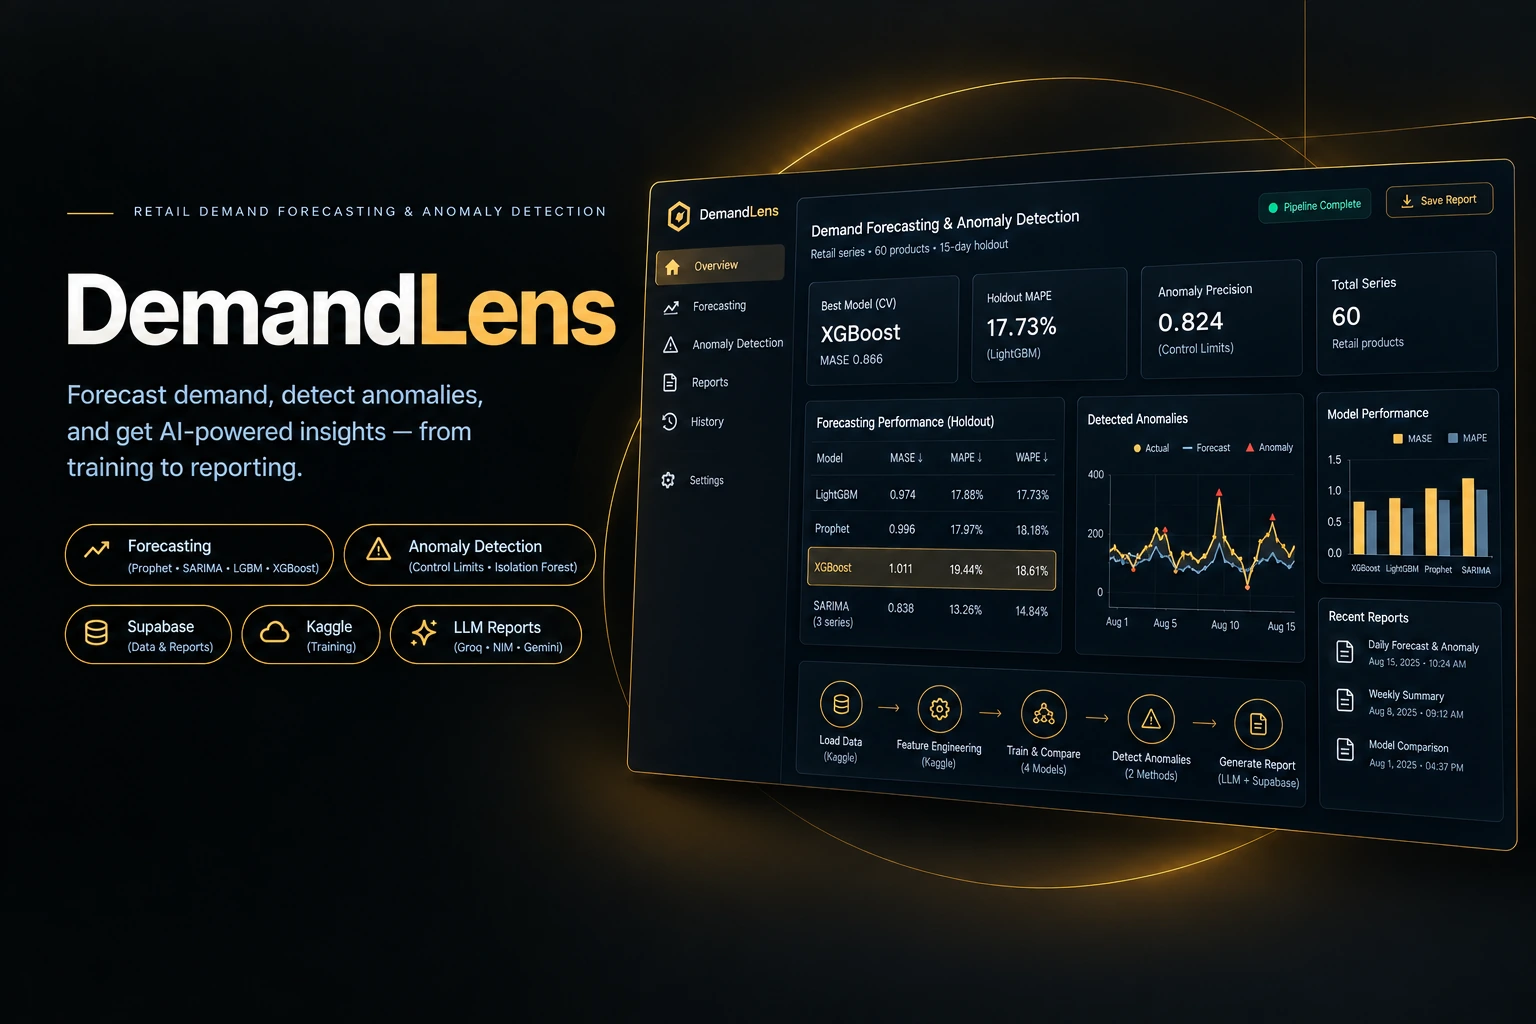
Benchmarks four forecasting models on 60 retail series, scores two anomaly detectors on injected anomalies, and verifies every number in an LLM-written report.
Recommender Systems
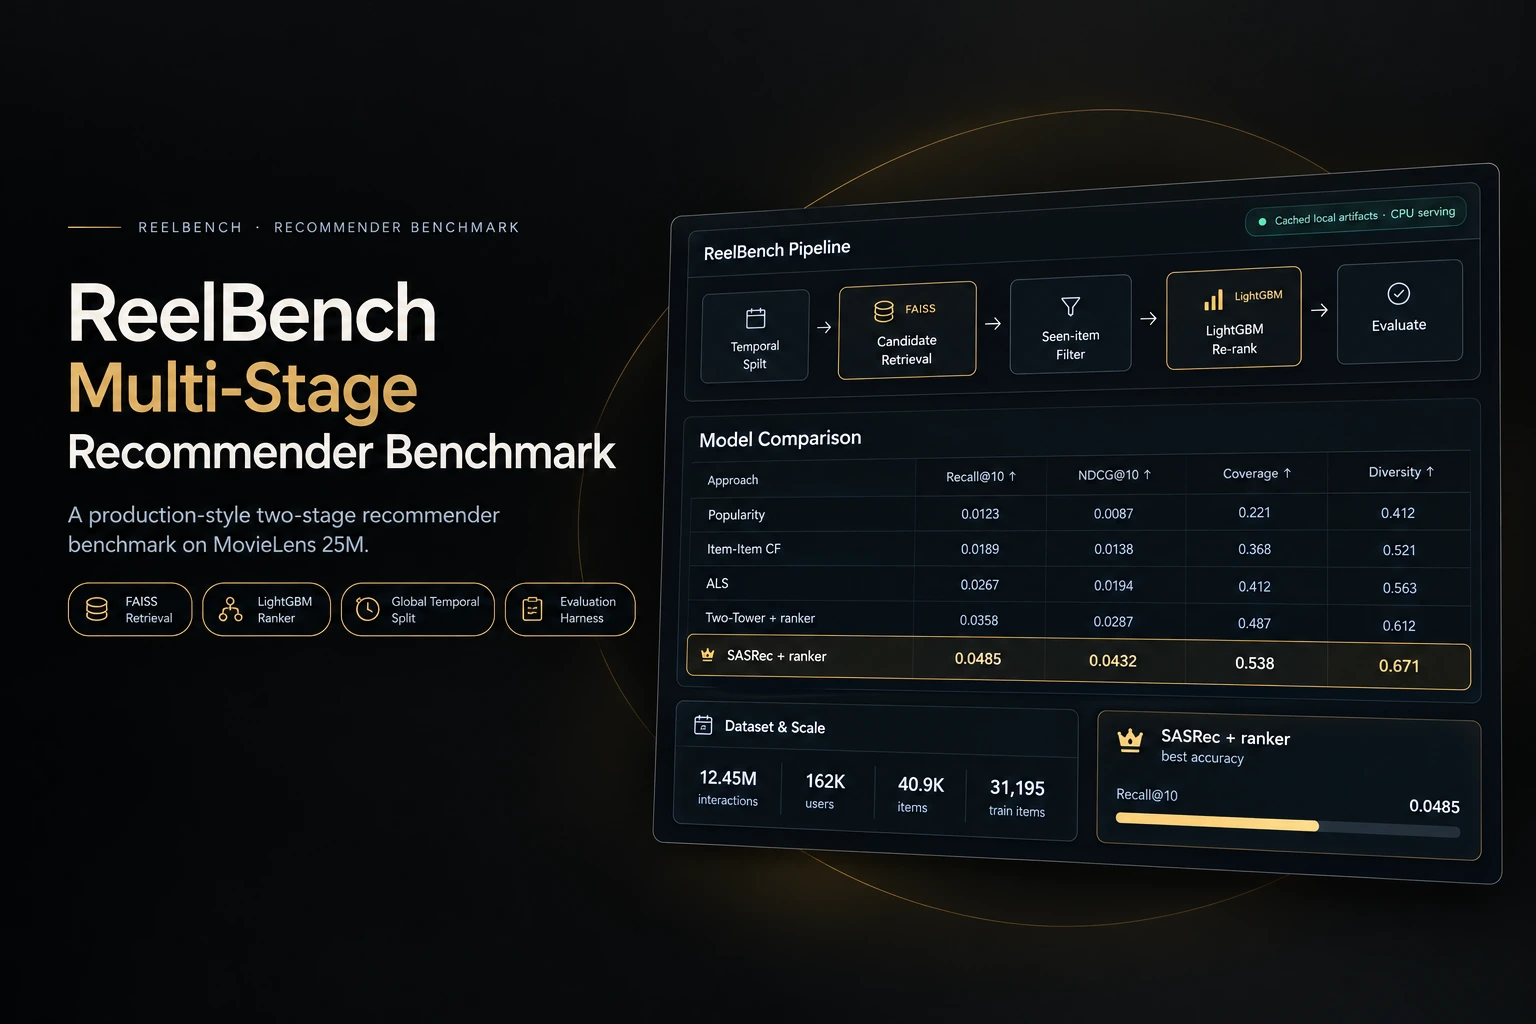
Five recommenders scored head to head on MovieLens 25M through one leakage-tested harness, trained on free-tier GPUs and served on CPU.
Causal Inference
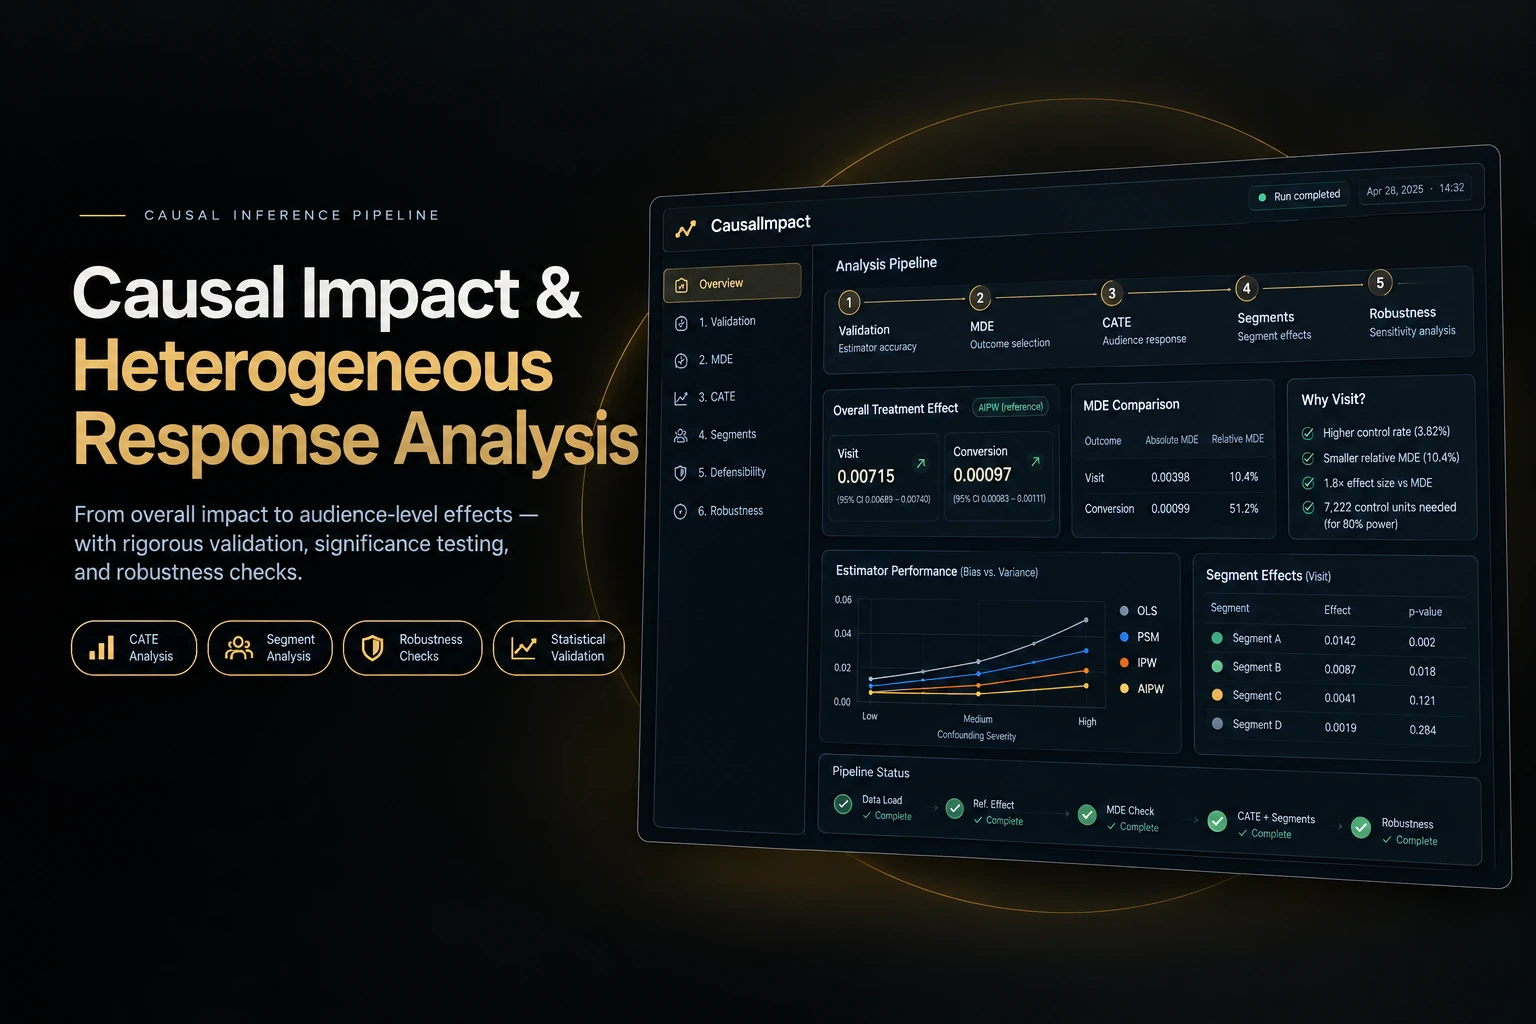
Tests four causal estimators against a reference effect on 14 million randomized ad rows, then checks which audiences responded and whether that survives multiple testing and hidden bias.
Experimentation
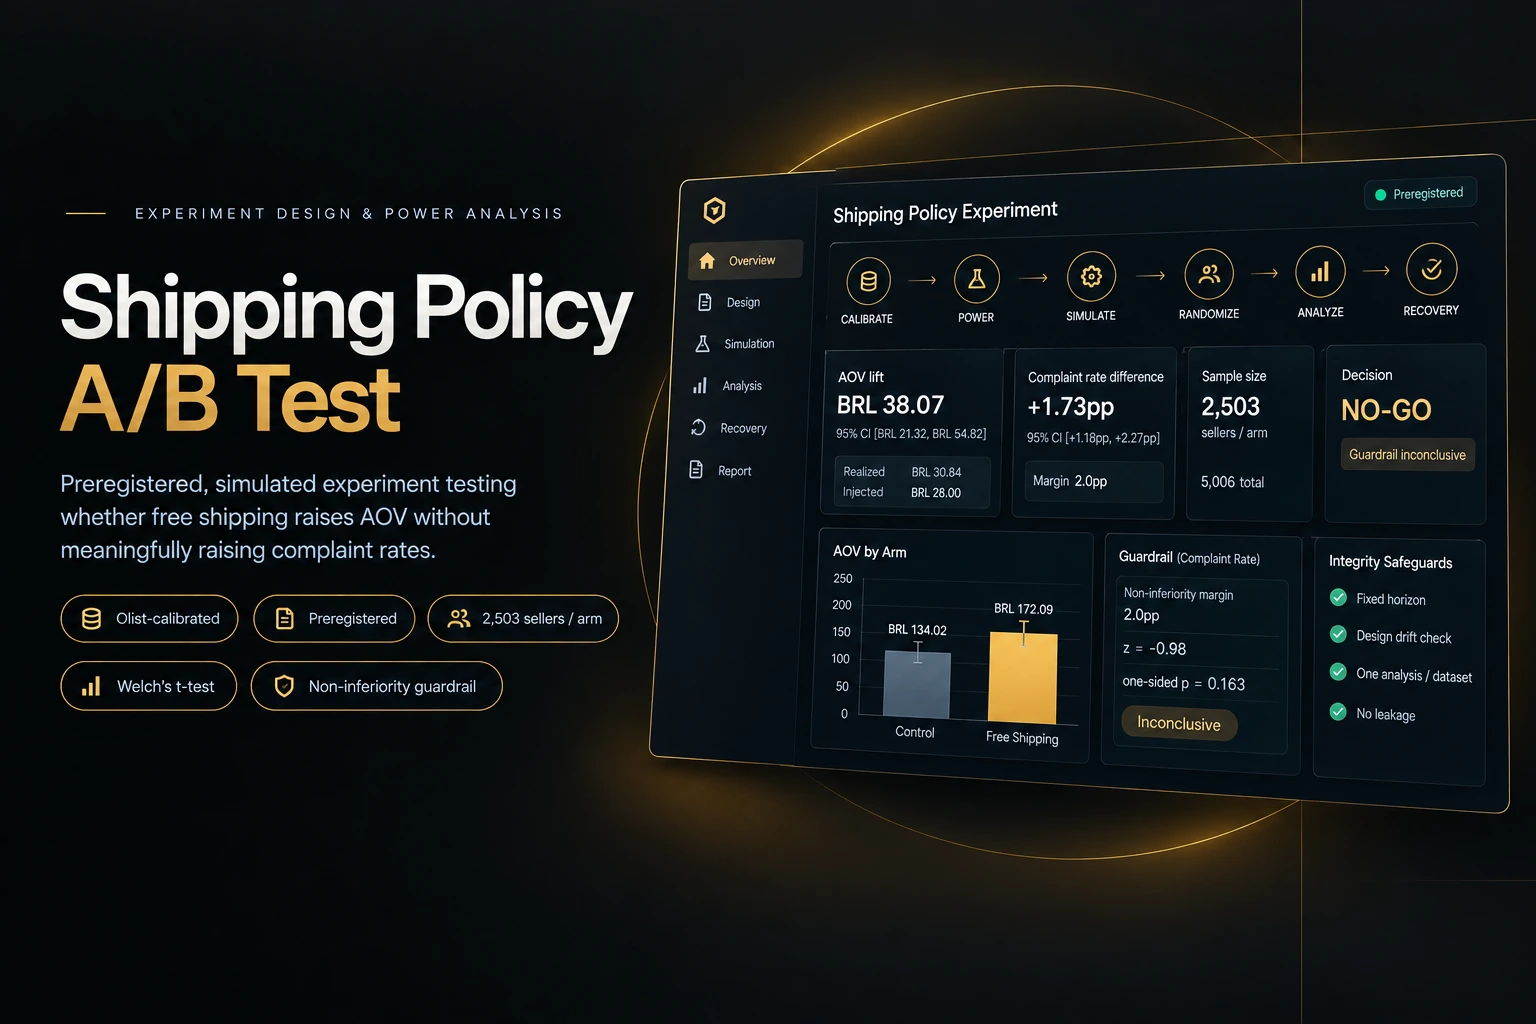
A preregistered A/B pipeline: metric, minimum lift, sample size, and tests are frozen before any data exists, then checked against an effect of known size.
Interested in working together?
Contact meGenAI / RAG
A Kubernetes Q&A system that answers only from the docs you ingest, with a gate at every stage that could let a bad answer through.
Most RAG demos stop at retrieve and generate. This one gates every stage: safety and topic checks run before any generation call, retrieval must clear a hard rerank threshold or the system says it has no grounded docs, and answers are safety-checked again before they are shown or cached.
AI Agents
An autonomous research agent that turns a company name into a sourced intelligence brief, and marks anything it cannot source as unknown.
Given a company name, the agent plans research across five fields (what it does, funding and ownership, recent news, competitors, risks) and writes a brief where every claim has a numbered citation. A Critic reviews coverage and can send it back to re-plan. A paired ablation measures what that loop buys and what it costs.
AI Agents / MCP
A GitHub issue triage server where the model can only propose. Nothing reaches GitHub until a human approves it.
An MCP client such as Claude, or a triage agent, can read GitHub issues and propose comments, labels, assignments, and closes. Ten tools face the model: five read-only and five that only queue a proposal in Postgres. No execute tool exists. A person reviews each proposal in a Streamlit dashboard, and every read, proposal, and decision is audit-logged.
MLOps
A credit-risk model that runs its own lifecycle: it scores, watches for drift, retrains, gates its own promotions, and rolls itself back.
A model does not stay good because it was good at launch. This pipeline simulates life after deployment on the Give Me Some Credit dataset: a recession is injected into 318 live batches of 200 rows, and the pipeline must notice, challenge the champion, and replace it with no human in the loop. A GitHub Actions cron advances the clock every 3 hours.
Causal Inference
Tests four causal estimators against a full-data reference effect before trusting any of them on a real segment-level question.
The Criteo Uplift dataset holds 13,979,592 rows from a randomized ad experiment. Even there, the raw difference in means overstates the covariate-adjusted reference effect (0.00715, 95% CI 0.00689 to 0.00740) by 45%, so the benchmark is a cross-fitted AIPW estimate on all rows. A subsample is then confounded on purpose to test whether naive OLS, matching, IPW, and AIPW recover that reference. Only then does it ask which audiences responded.
Experimentation
A preregistered A/B pipeline in which the metric, minimum detectable effect, sample size, and tests are locked before any experimental data exists.
Calibrated from the public Olist e-commerce dataset but simulated end to end. The question: does free shipping raise average order value (AOV) without raising complaint rates? The design, including a 2.0 percentage point non-inferiority margin on complaints, was committed before any simulation code existed. A population with a known injected effect (BRL 28.00 AOV, +1.2pp complaints) is then randomized and the preregistered tests run once.
Predictive Modeling
Predicts churn, then decides whom to target by expected profit instead of a raw probability cutoff.
Predicts 90-day churn from transaction history on the Online Retail II dataset and calibrates the score into a real probability. A customer is flagged INTERVENE only when expected profit clears the offer cost: churn probability times success rate times three months of spend, minus cost. A high-risk, low-spend customer can correctly be left alone.
Forecasting
Retail demand forecasting and anomaly detection benchmarked across four models, with an LLM report whose every number is checked against source data.
Benchmarks Prophet, SARIMA, LightGBM, and XGBoost on 60 retail series with a 15-day holdout, adds control-limit and Isolation Forest anomaly detectors, and generates an LLM report. Heavy computation runs in free Kaggle notebooks, and a light Streamlit dashboard reads only their saved outputs.
Recommender Systems
Five recommendation approaches scored head to head on MovieLens 25M through one leakage-tested evaluation harness.
A two-stage recommender, candidate retrieval then ranking, trained on free-tier GPUs and served entirely on CPU. The comparison table is the deliverable. The harness was built and unit-tested before any model existed, so popularity, item-item CF, ALS, a two-tower retriever, and SASRec are all scored by the same code on the same held-out split of 12.45M implicit interactions.